Jev Engineering for Coding Agents PDF: download, contents, and scope
The 12-page file titled Jev Engineering for Coding Agents is an independent synthesis of a proposed coding-agent harness. It discusses context selection, model routing, tool disclosure, retrieval reuse, conditional instructions, and programmable command gates.
It is useful as an engineering checklist and source guide. It is not an official TypeSafe white paper, a single installable Jev coding agent, or a complete API tutorial.
- Download the PDF or open the Google Drive copy ↗.
- Read the ten ideas without treating the PDF's examples as universal benchmarks.
- Follow the related Jev guide, coding-agent pattern, and a real model-routing project for next steps.
Jev Engineering PDF, official Jev docs, or a research paper?
These sources answer different questions. Use the PDF for the harness proposal, TypeSafe's documentation for the current Jev API, and the separate research paper to inspect the repository-search measurements cited in the PDF.
This page explains the independently compiled 12-page file. Download the PDF ↓ or open the source copy ↗.
For request formats and integration details, use TypeSafe's API reference ↗. The independent PDF is not an API reference.
The PDF cites this separate work when discussing reading and search in coding-agent trajectories. Read the paper ↗; its measurements are not a Jev benchmark.
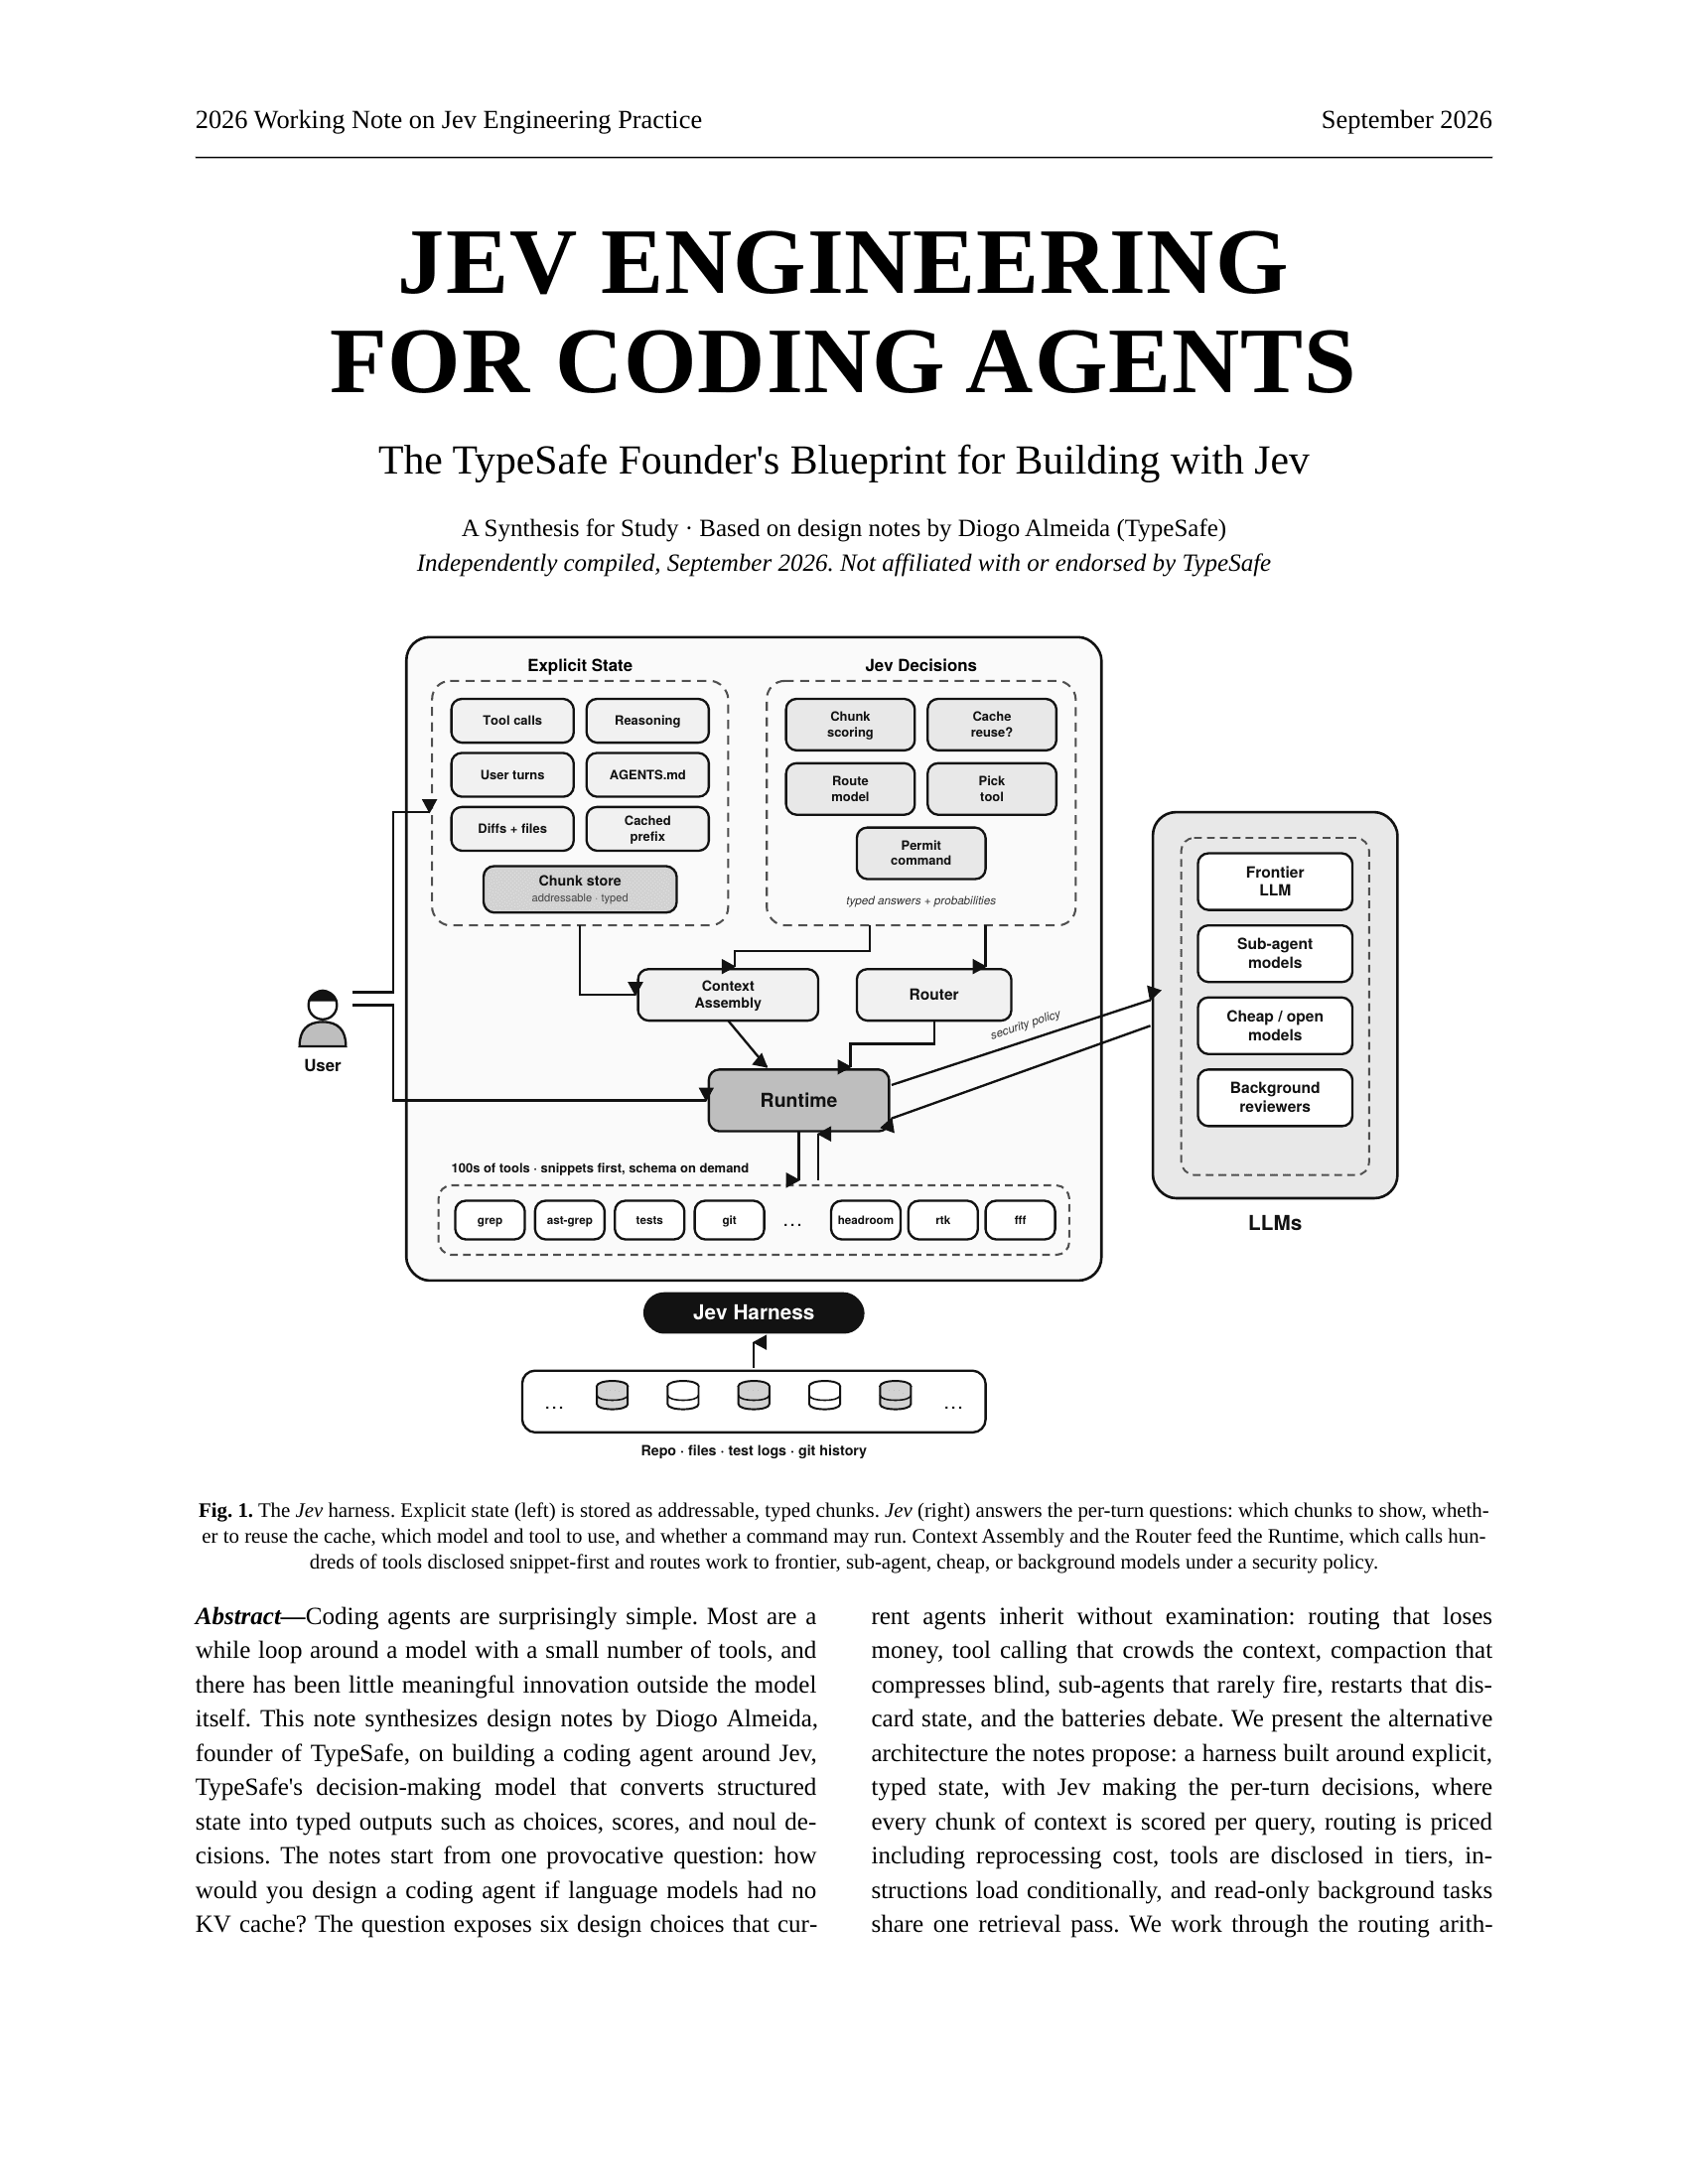
In one sentence: make agents read less, recompute less, and take fewer risky actions
This PDF is not a coding-agent product you can install. It is a harness design brief. The proposal turns “what should the next turn see, which model should handle it, and may this command run?” into runtime decisions that can be recorded, measured, and controlled.
Do not carry every file, tool description, and old message into every turn. Identify the question first, then hide, summarize, or fully show only what helps answer it.
Switching models is not automatically cheaper. Reprocessing a large context during a handoff can erase the savings from using a smaller model.
Let the agent recommend an action, then have the runtime inspect the script, permissions, and sensitivity before it chooses allow, ask, or deny.
You do not need to understand every term before starting. Use the paper as a checklist: is your agent rereading the same material, exposing too many tools at once, or sending high-risk and low-risk work through the same model path?
Ten steps from the Jev harness blueprint
Meet Jev: separate decisions from code generation
The LLM writes, the harness executes, and Jev decides what each turn sees, where the request routes, and whether it should run. Each decision can then have an input and an outcome you can trace.
Ask the question that breaks the default design: what if there were no KV cache?
If every turn had to reprocess its context, the agent would need a different architecture. The question forces you to inspect context size, handoffs, and cache assumptions.
Stop routing blind: a handoff can cost more
The PDF uses Opus → Sonnet → Opus versus pure Opus, 6.19 versus 4.15, as an example. Reprocessing the context during a handoff can erase the cheaper model’s advantage. Treat it as a cost model to test.
Follow the tokens
The document cites reading and search as 56.2% of tool turns and 46.5% of tokens, with code writing below 10%. Optimizing “find and read” may pay back before optimizing “write.” The related measurement is from the FastContext paper ↗.
Score every content chunk for the current question
The same chunk does not need to be fully injected every time. Hide it, show a short summary, show a long summary, or show the full content. Compress after the question is known, not before.
Disclose tools in tiers
Start with one-line descriptions for hundreds of tools, load a schema when needed, and load full documentation only for a one-off query. Tool “batteries” should not become a context charge on every turn.
Load instructions by condition, and keep them durable
When editing *.tsx, load the frontend style guide. When entering billing/, load that directory’s gotchas file. Conversation compaction should not erase these conditions.
Route by trust, not only by difficulty
Keep secrets, infrastructure, and high-privilege actions on a first-party frontier model. Public documentation and low-risk organization can go to a cheaper model.
Share one retrieval pass
One read-only retrieval result can serve cross-model review, eval generation, ELI5 explanations, and live progress pages. Background tasks should not search the same material again.
Gate every command with programmable policy
Do not inspect only the command name. Read the script and target first, then apply allow / ask / deny. Jev can provide a judgment; the runtime still owns authorization.
A version you can try now
You do not need to rewrite an agent all at once. Pick one decision that happens every day and has a measurable outcome:
Start with tool selection, code-chunk ranking, whether to escalate to a stronger model, or whether a human review is needed.
Save the input, candidates, final decision, outcome, latency, input and output tokens, and total workflow cost.
Load conditional instructions for common directories and add an allow / ask / deny check for commands. Compare the same task set before expanding the design.
If you use Codex or Claude Code, start with TypeSafe’s Agent Skill ↗ or inspect the community MCP implementation ↗. They provide integration entry points; per-turn context assembly, caching, and permission policy still belong in a harness you control.
Illustrative coding-agent task: changing a billing file
Suppose an agent must change a file under billing/. This is a design walkthrough based on the PDF, not a reproduced Jev implementation or a measured result.
- The harness records the task, candidate files, relevant repository notes, and allowed actions as explicit state. It loads the billing instructions only because the task touches that directory.
- For a specific question, Jev can score which context chunks to show and choose a model route from bounded options. The coding model receives the selected context and writes the proposed change.
- Before a proposed command runs, application code checks the target, policy, and authorization. Jev's judgment can inform that check; it does not grant permission by itself.
- The harness records the choice, executed action, test result, latency, tokens, and cost. Compare the same tasks with and without the new decision point before adding more routing rules.
A public coding-agent example: Jev Codex Router
The community Jev Codex Router repository ↗ shows one part of this design in code: Jev chooses a model and reasoning effort for each Codex model call from a bounded decision state, while the executing model receives the full Codex conversation. The repository is archived and its historical cost simulation is not a measured saving from this PDF's full harness.
Use it to inspect model-routing boundaries and fallback behavior. It does not establish that the PDF's proposed chunk visibility, shared retrieval, or command permission gates have been implemented or benchmarked together. Our source-linked project case → records the earlier author description.
How to read the numbers in the post
This is a social-post summary, not an end-to-end coding-agent benchmark after implementing the full 12-page blueprint. Re-test it against your own task set and baseline; TypeSafe’s workflow evaluations ↗ cover a separate evaluation scope.
This is an example under specific token, model, and price assumptions. Context size, caching, output length, and current prices can all change the result.
The first two figures come from FastContext trajectory analysis; the last is a working estimate in the PDF. They point to what to measure, rather than fixed ratios for every agent.
Original files and related sources
Read the ten-step guide first if you want the main idea. Open the original files when you want to verify details. The links below include the PDF, accessible text, official documentation, research paper, and community material.
Jev PDF download and coding-agent questions
Where can I download the Jev Engineering for Coding Agents PDF?
Use the local download button on this page for the 12-page PDF, or open the original Google Drive file in the Sources section. The accessible text mirror is also linked there.
Is the Jev Engineering PDF an official TypeSafe document?
No. The PDF identifies itself as an independent compilation and says it is not affiliated with or endorsed by TypeSafe. TypeSafe's official docs are linked separately.
What does the Jev coding agent PDF cover?
It covers a proposed harness boundary: deciding what context to show, how to route work, how to disclose tools, how to reuse retrieval, and how to gate commands. The application runtime still performs the actions.
Does this Jev PDF include a complete API or Claude Code tutorial?
No. It gives design ideas and experiments rather than a single copy-and-run implementation. Use the official API quick start and a concrete project case for runnable steps.
Which Jev PDF idea should I test first?
Start with one repeated decision such as tool selection, context ranking, model escalation, or human-review routing. Record the input, candidates, decision, outcome, latency, tokens, and cost before expanding the harness.
Is the PDF a coding-agent benchmark?
No. Some figures are examples or author-reported summaries. Treat them as hypotheses to test against your own task set, not as a universal speed, cost, or quality guarantee.
Use the Jev Engineering PDF as an engineering checklist
The useful idea in this PDF is making a coding agent's “what to see, where to route, and whether to execute” decisions observable. Validate one workflow first, then expand the harness.
Browse more sourced Jev resources →